AI-Powered Offering Memorandum Generation for CRE Brokers
AI automates the tedious assembly work that has always bottlenecked commercial real estate brokers.
The offering memorandum is the document on which a listing assignment lives or dies. A brokerage without the ability to produce an institutional-quality OM cannot credibly compete for larger mandates, and it cannot respond to time-sensitive processes where a seller expects a packaged, professional presentation within days of signing an engagement letter. The standard structure of an OM is demanding by design: a cover page, an executive summary, a property overview, a location and demographic narrative, a financial summary, a rent roll, a market overview, and tenant profiles, with each section drawing on a different data source and requiring its own synthesis. A typical OM runs 30 to 80 pages and carries the seller's financial projections, operating statement, rent roll, market context, and investment thesis, all of it material a buyer's analyst will scrutinize line by line before a letter of intent ever gets drafted.
The labor in producing that document has never been a matter of knowing what belongs in it. A broker who has run a listing process knows the structure cold. The labor sits in the assembly: pulling comparable sales, formatting financial statements into a presentable summary, writing a market narrative that reads as informed rather than generic, holding the document to the firm's brand standards, and reconciling numbers that arrive from three or four different sources so that the rent roll matches the operating statement and the operating statement matches the investment thesis. That assembly work has always eaten up the scarcest resource in a small or mid-size brokerage: senior analyst time. The person has to be capable enough to be trusted with the document but valuable enough that every hour spent formatting is an hour not spent sourcing the next deal.
It takes days of analyst effort to produce one OM, and that sets a hard ceiling on how many listings a team can market at once. That ceiling has nothing to do with the firm's budget or the strength of its client relationships. It is a constraint on document throughput, plain and simple: a team can only originate as many active listings as it can simultaneously package to a professional standard. Because the cost of producing an OM is roughly fixed regardless of the size of the asset behind it, and the analyst hours required to package smaller mandates properly cannot be justified against the fee they generate, brokers routinely self-select away from those deals, even though they often have merit. The bottleneck is structural, and it has shaped which deals brokerages choose to pursue for as long as the OM has been the standard currency of a listing assignment.
Generating an Offering Memorandum with AI
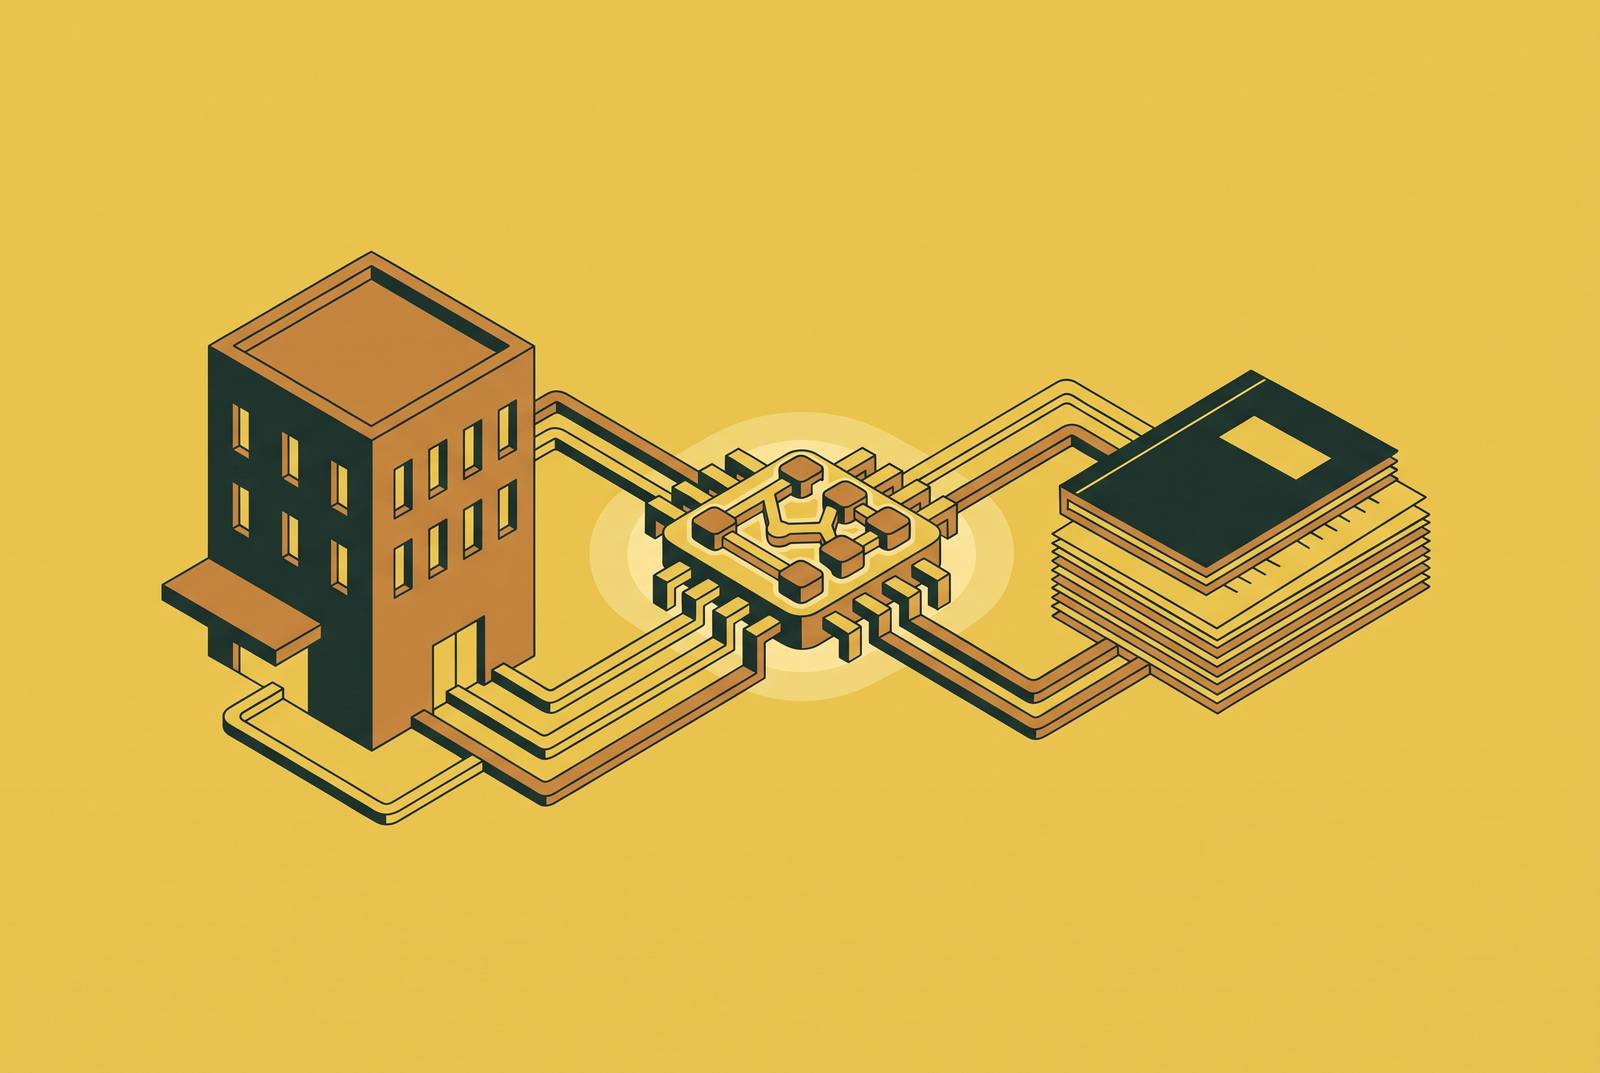
AI's involvement in the OM workflow runs in two directions that serve opposite sides of a transaction, and the distinction matters for understanding what the technology actually does. On one side sits extraction: software reads a completed OM, pulls out deal economics, validates the seller's assumptions against market data, flags inconsistencies, and populates an underwriting model in Excel. That is the buyer's workflow, built for a buy-side analyst who needs to turn a finished document into numbers fast. On the other side sits generation, the broker's workflow, where the process runs in reverse. The broker supplies property data, a case study, or a set of structured inputs, and the AI produces the narrative sections, the market write-up, the framing for the financial summary, and the shell of the document itself. This article concerns the generation side, but understanding the extraction side clarifies the boundary: both rely on the same underlying capability, which is that AI can now parse prose, identify a selling point versus a risk factor, and pull information embedded in paragraphs rather than only from structured fields and spreadsheet cells.
That capability lines up neatly with where analyst time has always gone. The sections of an OM that consume the most hours, namely the property narrative, the market overview, and the tenant summary, are exactly the sections AI drafts fastest, because they are tasks of synthesis. A property description and its investment highlights can be generated from structured inputs such as square footage, year built, tenancy mix, recent capital expenditures, and location, with the broker then editing for positioning and tone. A market overview and demographic narrative can be synthesized from data the broker supplies, comps, submarket vacancy, and absorption figures, turned into readable prose. The broker has to supply verified comp data rather than asking the AI to locate its own, because stale or fabricated comps are the single most common failure mode in this workflow. Tenant profiles and lease summaries draw their key terms from lease abstracts the broker provides, with the AI formatting those terms into the OM's tenant section. Financial summary framing works the same way: the AI structures how net operating income, cap rate, and a returns narrative get presented, built entirely around numbers the broker has already input. It does not price the asset. Pricing judgment, comp selection, the framing of the deal to a specific buyer pool, and the final review of every figure remain the broker's work, and that boundary is what makes the generation side trustworthy.
How the AI-assisted OM workflow runs in practice
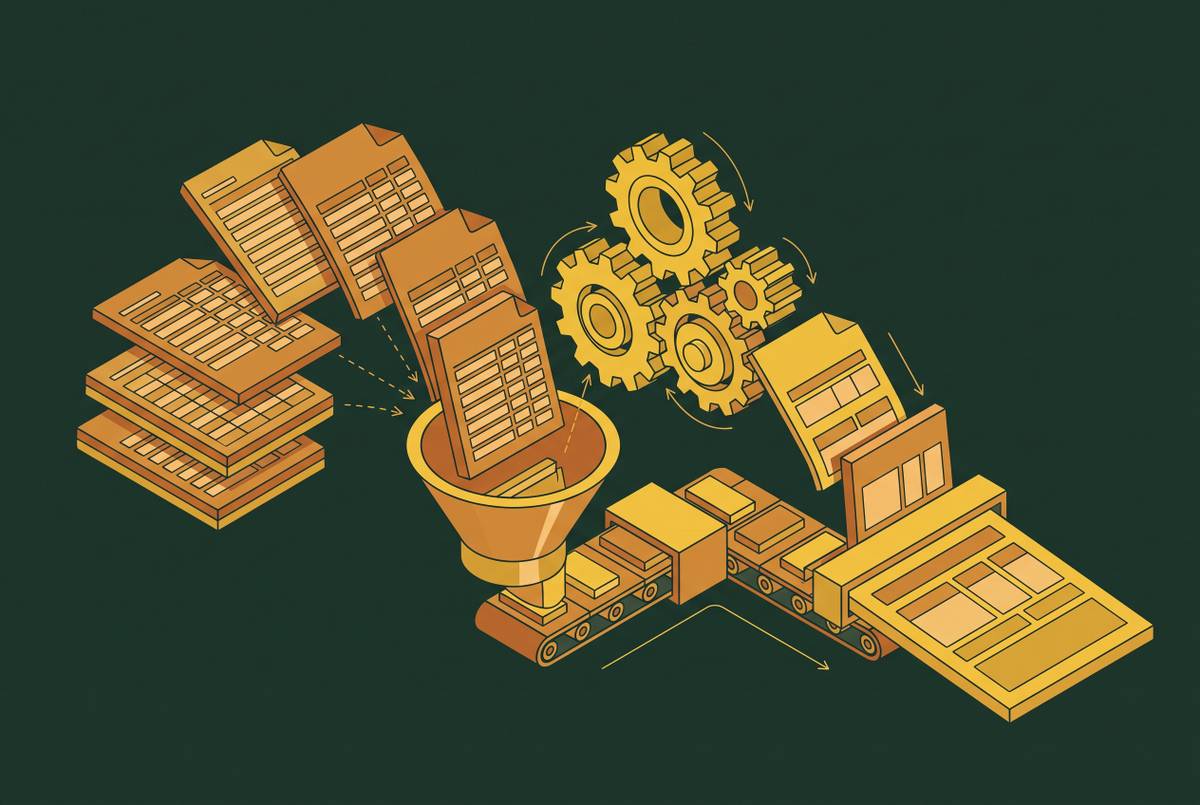
The workflow that compresses OM production time is not a single piece of software but a layered process, where structured inputs go in, AI produces a draft of each section, the broker reviews and repositions that draft, and a client-ready document comes out the other end.
The first step is assembling the inputs the AI will work from. That means a property data sheet covering address, asset type, size, year built, unit or tenant count, recent renovations, and amenities. It means a rent roll that the broker has verified, listing tenant names, lease terms, rent, escalations, and options. It means a trailing twelve-month operating statement and any supporting financials, a comp set the broker has pulled and verified personally, submarket data on vacancy, absorption, and asking rents sourced from licensed providers, and whatever photos, maps, and site plans already exist for the property.
The second step runs those inputs through an AI generation layer, and brokers have more than one way to do this. Arturo Parada of the A.CRE team built the A.CRE Offering Memorandum Creator Assistant: feed it a structured real estate case study, and it turns the analytical data into a professionally structured document with narrative context woven through it, so each case study feeds both the numbers and the prose built around them. A broker can also paste inputs section by section into a general-purpose tool such as Claude or ChatGPT, paired with a saved OM prompt template, and get each section produced independently. A harness is the application the broker actually works in, a model does the reasoning, connectors link to deal files, CRM records, or property management data, CRE-specific knowledge is encoded as agent skills that structure how OM sections should read, and the broker reviews everything that comes out. CRE data providers including Green Street, MSCI Real Assets, Yardi Matrix, ATTOM, and Regrid, along with capital markets data providers such as Moody's, now publish their own MCP servers. Licensed market data can plug directly into Claude or ChatGPT rather than being pasted in from manually exported spreadsheets. Yardi's Virtuoso connector for Claude, the first property management system with an MCP connector on the Anthropic marketplace, lets an AI agent query live Yardi data conversationally, so rent roll data can flow into the OM generation workflow without a manual export step.
The third step is where the AI produces the document's sections: an executive summary with investment highlights keyed to the specific asset, a property overview narrative, a location and demographic write-up, a market overview synthesized from the comps and submarket data the broker supplied, a tenant summary built from lease abstracts, and a financial summary whose numbers are broker-supplied but whose presentation the AI structures. Some platforms push this further on the formatting side: IntellCRE auto-populates photos, maps, comps, and financial summaries without manual reformatting, and includes AI-generated market reports automatically, cutting down on the research hours a broker would otherwise spend assembling that context by hand.
The fourth step is broker review, positioning, and the application of brand standards, and this is not a step that gets skipped or compressed. The broker reads every section for accuracy. That reading is where the broker's judgment earns its keep, not a formality layered on top of the AI's draft. Investment highlights get repositioned according to the broker's read of the specific buyer pool and what that pool actually prioritizes. Brand standards, fonts, colors, disclaimers, get applied separately, since a tool like the A.CRE assistant generates its structured drafts around a fictitious brokerage name and industry-norm assumptions, leaving the firm's actual branding for the broker to apply. Only after that review does the document get packaged and go out the door.
A parallel development is reshaping the financial summary step specifically. More AI now runs inside Excel directly, with Claude for Excel, ChatGPT for Excel, and Endex all operating within the workbook itself. So the broker no longer has to export financial data to a separate tool for narrative framing, and OM financial summary generation becomes a single workflow that stays inside the model the broker already trusts.
The capacity arithmetic: what OM compression means for deal volume and firm economics
Compressing the time it takes to produce an OM does more than save hours on any single deal. It raises the ceiling on how many deals a team can pursue at once, and that shift changes which mandates are worth taking. The time saved concentrates in the same sections that always consumed the most analyst hours, the property narrative, the market overview, and the tenant summary, which happen to be the sections AI drafts fastest. When the time required to produce an OM drops sharply, the fixed cost of producing one relative to the size of the deal behind it changes with it, and smaller deals that were previously uneconomic to pursue with a full, professional OM become viable again.
The throughput effect is already visible in adjacent brokerage work. Brokers using AI for broker opinion of value work have reported a threefold increase in BOV throughput using Claude, so teams can take on smaller deal sizes that would not have penciled out under the old labor cost structure. A team that produces more OMs per quarter without adding headcount competes for a larger share of the market, because it can say yes to engagements that a slower-moving competitor has to decline. Mid-market firms are finding that AI tools now give them capabilities that once required hiring more analysts, so a smaller investment sales team working with AI can match the deal volume of a larger team that does not have it. Lev, a CRE-specific AI and data platform that converts property financials and deal inputs into lender-ready memos and marketing documents, is one example of where that capacity is being built.
The cost-to-value calculation for a small investment sales team favors adoption by a wide margin. General-purpose AI tools such as Claude Team and ChatGPT Business cost meaningfully less on standard annual-billed seats than on premium seats, based on pricing Anthropic and OpenAI published on their own pricing pages in October 2026. Measured against analyst hourly cost and the hours saved on a single OM, payback comes quickly, and most brokerage teams that produce multiple OMs per quarter will recover the cost of the tool on one document alone. Every additional OM a team can produce without adding headcount after that point is pure surplus that flows directly into capacity and margin.
Where AI-generated OMs fall short
The primary failure mode in an AI-generated OM is a confidently presented number that happens to be wrong, stale, or fabricated outright, and that risk is what makes the broker's verification discipline the non-negotiable piece of any AI-assisted OM workflow. Large language models write fluently, but they should never be trusted to supply specific figures such as cap rates, vacancy rates, or comp sale prices pulled from their training data, because those figures will be out of date or simply invented. The practitioner protocol follows directly from that risk: the broker provides the comp set explicitly, supplying verified exports and asking the AI to format the narrative around them, and never asks the AI to go find its own comps. Reading a document and analyzing it are not the same task. Reading means extracting text and numbers from a source. Analysis means interpreting those numbers in context, testing assumptions against market data, and catching structural inconsistencies before a buyer's analyst does, and that analytical layer belongs to the broker, not the AI. At the investment committee level, people still meet AI-generated analysis with real skepticism in high-stakes financial decisions, so the financial summary in any OM has to be the broker's own work, with AI structuring and presenting numbers the broker has already derived rather than supplying independent financial conclusions of its own.
That discipline translates into a short list of elements a broker has to verify against source documents before any OM leaves the firm. The rent roll has to match the executed leases exactly: an AI summary of a lease abstract can misread an escalation structure, mistaking fixed increases for compounding ones, or drop an option condition the tenant actually holds. The financial summary figures, including NOI, cap rate, and return projections, have to be traced back to the broker's own underwriting model. Every sale cited in the comp narrative has to be a transaction the broker can independently source, with nothing invented or estimated by the AI standing in its place. Submarket vacancy, absorption, and asking rent figures have to come from licensed, dated sources the broker controls directly, not from whatever the model recalls on its own. Finally, the disclaimers, confidentiality notices, and offering terms have to meet the firm's legal standards and pass through counsel's review, since no AI-generated language in that category should go out unreviewed. None of this diminishes what the generation side of the workflow accomplishes. It defines the line past which judgment takes over from speed, the same line that has always separated a professional offering memorandum from a document that merely looks like one.